VoZii turns your voice into text anywhere you can type — a chat box, an email, an
IDE, a form field. Press and hold your hotkey, talk, let go: the transcription lands
right at the cursor. The Whisper model runs on your own machine, so nothing you
say ever leaves it — no upload, no subscription, no waiting on a server.
It ships as a single 32 MB .exe. No Python to install, no runtime to set up.
The Whisper model stays loaded in RAM between dictations, so there's no per-use lag,
and an optional local LLM (via Ollama) can clean up filler words
and formatting — still 100 % offline.
✨ Highlights
- 🎙️ Push-to-talk, your key — any keyboard or mouse button (default
Ctrl+Shift+Space); press-and-hold or toggle
- 🔒 100 % local & private — no cloud, no API keys, no telemetry; works with the network cable pulled
- ⚡ No per-dictation lag — the model stays resident in a persistent
whisper-server, saving ~2–10 s every time
- 🚀 GPU-accelerated — NVIDIA (CUDA) & AMD (Vulkan), automatic detection, CPU fallback; 5–10× faster with a GPU
- 🌍 9-language UI + 18 dictation languages + auto-detect — the interface follows your Windows language; dictation covers all ~99 Whisper languages
- 🎯 Speed / Accuracy toggle — greedy decoding for snappy dictation, beam search when you want it exact
- 🧹 Hallucination filter — silence and phantom phrases ("thanks for watching", …) are dropped, not typed
- 📋 Clipboard-safe — inserts at the cursor and restores whatever was on your clipboard afterwards; if another app is holding the clipboard, VoZii retries instead of pasting the wrong text
- 🕘 History — your last dictations are re-copyable from the tray menu (local, toggleable)
- 🧠 Optional AI cleanup — a local Ollama model removes filler, fixes grammar, or turns speech into a polished prompt
- 🛡️ Verified downloads — models and binaries are checked against pinned SHA-256 hashes before they run
- 🩺 Self-healing — a watchdog re-arms the global hotkey and reopens the microphone stream if Windows drops either, so long sessions don't need a restart
- 📦 Single 32 MB file — no installer, no dependencies, dark UI in the haZii design language
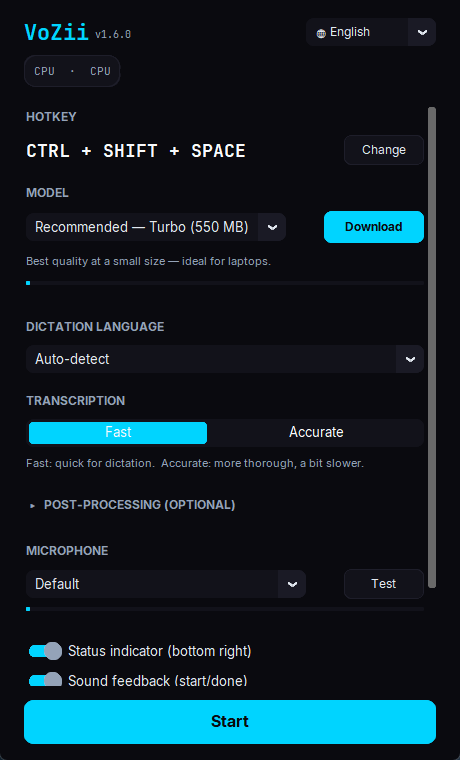
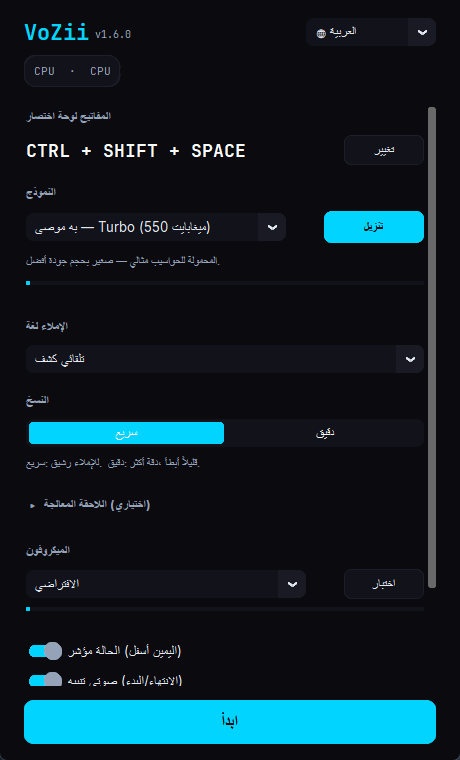
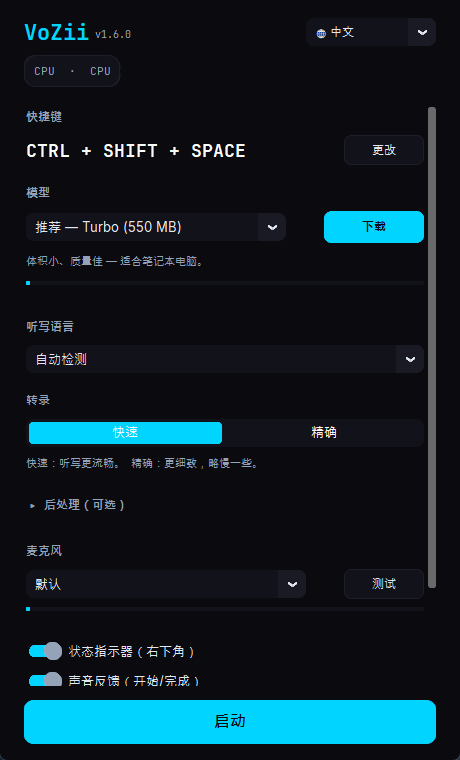
🖼️ Screenshots
> One window, many languages — the UI is fully translated (with right-to-left layout for
> Arabic) and picks your Windows language on first run. Switch any time with the 🌐 picker.
⌨️ How it works
- Hold your hotkey (default
Ctrl+Shift+Space).
- Speak into your microphone — a small status overlay shows
● REC.
- Release the hotkey — VoZii transcribes locally (
· · ·) …
- … and types the text at your cursor. Optionally, a local LLM cleans it up first.
Right-click the tray icon for your last transcriptions, settings, the log, or
to quit. The status overlay reports everything at a glance — CLIP (text is on the
clipboard, no field was focused), SHORT / EMPTY, or ERR:MIC / ERR:WHISPER.
What's inside
| |
|---|
| 🗣️ Whisper models | Fast (Tiny, 75 MB) · Recommended (large-v3-turbo Q5, ~550 MB) · Best (large-v3-turbo, ~1.5 GB) |
| 🌐 UI languages | Deutsch · English · Español · Français · Português · Русский · 中文 · 日本語 · العربية |
| 🎧 Dictation | 18 hand-picked languages + Auto-detect covering all ~99 Whisper languages |
| 🖥️ Compute | NVIDIA CUDA · AMD Vulkan · CPU fallback — auto-detected and cached |
| 🎚️ Decoding | Fast (greedy) for everyday use · Accurate (beam search) when it matters |
| 🔧 Extras | Persistent audio stream (no clipped first syllable) · microphone level test · autostart with Windows |
| 🆕 v1.8 | Toggle mode with auto-stop on silence · custom vocabulary (names & jargon) · update notifications · whisper.cpp 1.9.2 |
🚀 Get VoZii
- Download
VoZii.exe from the latest release.
- Double-click — the settings window opens; your GPU is detected automatically.
- Download a model (~550 MB the first time; the Recommended turbo model is a great default).
- (Optional) Test your microphone — a live level meter confirms the signal.
- Click Start — VoZii lives in your system tray, ready whenever you hold the hotkey.
> SmartScreen warning? That's expected for an unsigned .exe. Click More info →
> Run anyway, or right-click the file → Properties → Unblock → Apply.
Requirements
- OS: Windows 11 (64-bit)
- RAM: 2 GB free (4 GB recommended for larger models)
- GPU: optional but recommended — NVIDIA GeForce (CUDA), AMD Radeon (Vulkan), or integrated; CPU works too
- Data: models, config and log live under
%LOCALAPPDATA%\VoZii (or next to the
.exe if a config.yaml/whisper-cpp folder already sits there — portable installs)
🩺 Troubleshooting
| Symptom | Likely cause | Fix |
|---|
| SmartScreen warning on first launch | Unsigned .exe (expected) | More info → Run anyway |
| Recording works, but no text appears | Smart App Control blocks the unsigned speech engine (0xC0E90002 in the log) | Windows Security → App & browser control → turn Smart App Control off — VoZii shows a dialog explaining this since v1.8 |
| No text on a fresh Windows | Microsoft VC++ Runtime missing (0xC0000135) | Install the VC++ Redistributable x64 — VoZii detects this and shows a download link |
| App won't start at all | AV/AppLocker blocks the onefile extraction in %TEMP% | Check %TEMP%\vozii_boot_error.log; allow the app or adjust the policy |
Full guide with log locations and more cases: docs/TROUBLESHOOTING.md
🧠 AI post-processing (optional)
VoZii can polish transcripts with a local LLM through Ollama —
no text ever leaves your machine. A one-click setup inside VoZii installs Ollama, starts
it, and pulls a model (with live progress and a cancel button). Pick a tier to match your
hardware:
| Tier | Model | Size |
|---|
| Fast | llama3.2:1b | ~1.3 GB |
| Balanced (default) | qwen2.5:3b | ~2 GB |
| Best | gemma3:4b | ~3 GB |
Three modes:
- Off — raw Whisper output.
- Smart — removes filler, fixes grammar, and understands spoken commands like
"as a list", "as an email", "heading", "as code", "new paragraph".
- Prompt — rewrites what you said into a clean, well-structured AI prompt.
If Ollama isn't installed or a call fails, VoZii silently falls back to the raw transcript —
you never lose a dictation.
🔒 Privacy
VoZii runs entirely on your machine:
- ✅ No audio is ever sent to a server — transcription is fully local
- ✅ No internet needed to run (only once, to download a model)
- ✅ No telemetry, no analytics, no accounts
- ✅ Optional update check asks GitHub for the latest version number only —
one request at startup, can be switched off in settings
- ✅ History (last 50) stays in a local
history.json — toggleable and clearable in settings
🛠️ Build from source
Python 3.12+, quality-gated by ruff and a pytest
suite on GitHub Actions; releases are built and published automatically on v* tags.
python -m venv .venv && .venv\Scripts\activate
pip install -r requirements.txt
python -m src.main            # run VoZii
pytest -q                     # run the test suite
python scripts/build.py       # build the single-file VoZii.exe (PyInstaller)
The tree is a clean set of single-purpose modules — hotkey.py, transcriber.py,
text_processor.py (Ollama), filters.py (hallucinations), i18n.py, overlay.py,
downloader.py (SHA-256 pins) and friends under src/.
☁️ Why local instead of the cloud?
| VoZii (local) | Typical cloud dictation |
|---|
| Your voice | never leaves the PC | uploaded to a server |
| Cost | free, no subscription | monthly fee / per-minute |
| API key / account | none | usually required |
| Offline | ✅ works fully offline | ❌ needs a connection |
| Latency | local, model stays in RAM | network round-trip |
📄 License
MIT — see LICENSE. Third-party components are listed in
THIRDPARTY-LICENSES.md. VoZii uses
whisper.cpp by Georgi Gerganov for local
transcription.
Built by
haZii · // code: haZii.org